Cloudflare launches Clairic, the first 'System One' extraction model: typed values in one pass, no output tokens
- Who: Cloudflare, announcing on its official blog on October 19, 2026.
- What: Clairic, the first "System One" extraction model — a preview on Workers AI as
@cf/cloudflare/clairic; open-weights release planned "soon," no date given. - How it works: one parallel forward pass over a
state(text + up to 4 images) and typedfields; no output tokens, so only input is billed — $0.10 per million input tokens, 65,536-token context window (per Cloudflare's model docs). - The four jobs: extract (spans with character offsets + confidence), compute (numbers, dates, durations, lists), estimate (median + 80% interval inside declared bounds), forecast (one estimate per future step).
- The numbers: Clairic → Clef → GLM-5.3 claims cascade: 19.3s vs 61.7s all-LLM (69% faster); $6,032 vs $11,740 per million claims (49% cheaper). TSA forecasting test: 3.3% average error over 21 days, 17 of 21 actuals inside the 80% interval.
- The limits: early checkpoint — weak multi-step arithmetic, estimates need evidence in the input, calibration measured not guaranteed, forecasting basic. Missing fields return
nullwith aguess, never fabricated text.
The model that doesn't generate text
Cloudflare announced Clairic on October 19, calling it the first model in a new class: System One extraction models. It is available as a preview on Workers AI as @cf/cloudflare/clairic, callable from a Worker with env.AI.run() or through the REST API. The company says it intends to release the weights openly "soon," after more checkpoint work — no date given.
The core idea is a break from the LLM playbook. A request pairs a state — the text to read, plus up to four optional images — with a map of typed fields. You name each field, give it a type and a plain-language instruction, and Clairic returns one typed answer per field from a single parallel forward pass. There is no reasoning step and no generated tokens, so billing applies to input only: $0.10 per million input tokens, per Cloudflare's model docs, with a 65,536-token context window and vision support.
Extract, compute, estimate, forecast
Cloudflare gives the model four jobs. It extracts values as text spans copied from the input — each with character offsets and a confidence score. It computes numbers, dates, datetimes, durations, and lists read from or worked out from the input, following the rules of their type. It estimates values the input doesn't state but gives evidence for, returning a distribution inside bounds you declare: a median and an 80% interval (p10 to p90), with all 99 percentiles on request. And it forecasts future values of a series, one estimate per step ahead.
Every scalar answer carries p_null — the probability the value isn't in the inputs — plus a confidence score. When the input doesn't determine a field, Clairic returns null instead of a plausible-sounding guess, and shows what it would otherwise have picked in a separate guess field. Because it generates no tokens, the company argues, it can't mistype an answer or hallucinate the way an LLM does — though it can still be wrong, and answers are, in Cloudflare's own words, guaranteed to be well formed, not necessarily correct.
The pipeline test: 69% faster, 49% cheaper
The announcement's headline numbers come from a damaged-product claims workflow that chains three stages: Clairic extracts typed values from a support email, Cloudflare's Clef decision model resolves the claim, and GLM-5.3 writes the reply. Against an all-GLM-5.3 version of the same pipeline, the cascade finished in 19.3 seconds versus 61.7 seconds — 69% less time, about 3.2x faster — and cost $6,032 per million claims versus $11,740, or 49% less. Clairic and Clef handled extraction and the decision in 0.46 and 0.22 seconds combined, where GLM-5.3 took 38 seconds for the same two steps. Notably, Clairic's repair-cost estimate was identical on every run, while GLM-5.3's changed ($250, $250, and $220, with different ranges each time) — and in the all-LLM version, both Gemma 4 and Qwen failed the task outright, unable to derive values like the repair cost from the inputs.
For forecasting, Cloudflare reports a 21-day test predicting next-day TSA airport checkpoint screening counts from the public series. The forecasts were off by 3.3% on average, and 17 of the 21 actual counts landed inside the model's 80% interval — roughly what an 80% interval should do. On October 14, the actual count was 2,419,474 against a predicted median of 2,419,283. The misses are instructive: three of the four days outside the interval fell on Columbus Day weekend, when more people flew than the series suggested — Clairic reads patterns in the data, but it can't see holidays the data doesn't show.
Where it sits in the model landscape
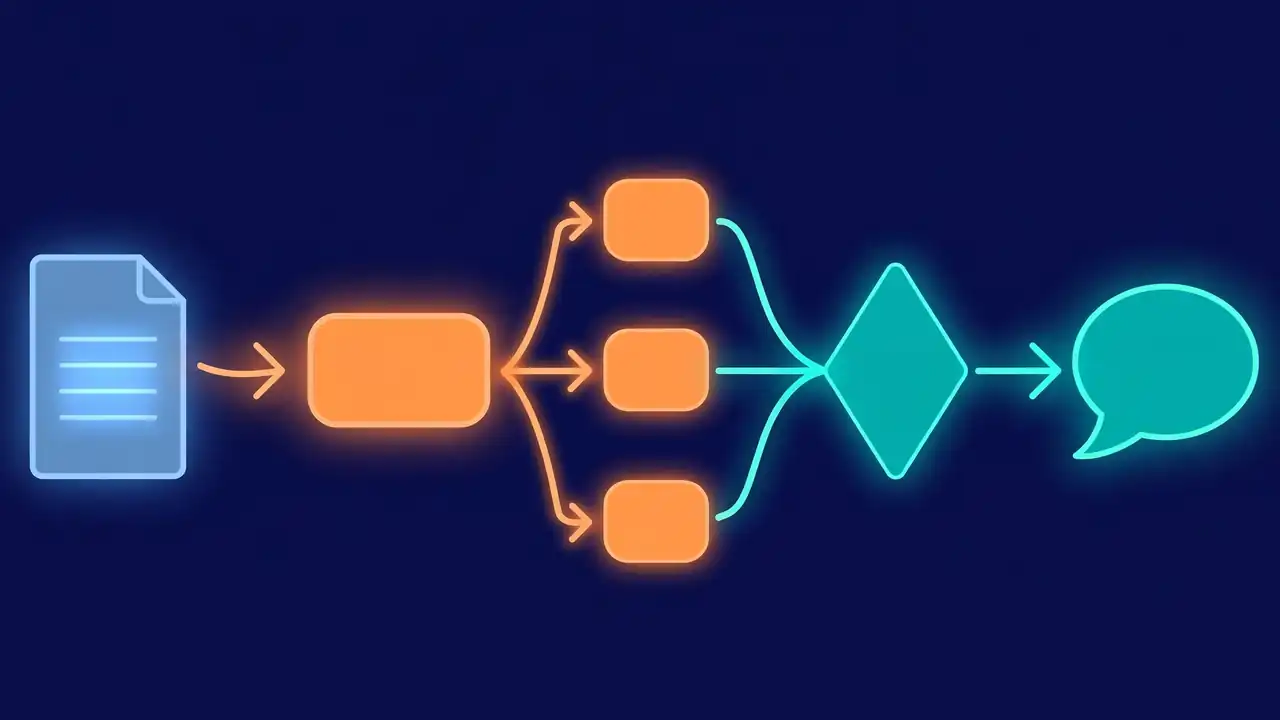
Cloudflare frames this as a new pillar in its System One push. The concept traces back to TypeSafe's announcement of System One models a month ago, inspired by Daniel Kahneman's Thinking, Fast and Slow: fast, precise models for narrow jobs, priced accessibly, rather than deliberative System Two reasoners. TypeSafe's Jev decision model kicked off the category; Cloudflare's own Clef decision model followed on October 1, which Unite.AI reports was open-sourced on Hugging Face under Apache 2.0. The taxonomy Cloudflare now draws: extraction models predict values (Clairic), decision models make choices among options (Jev, Clef), LLMs write and reason. The intended workflow is a cascade — extraction turns raw input into typed values, a decision model turns values into decisions, an LLM turns the decision into words.
The fine print
Cloudflare is unusually candid about the current endpoint being an early checkpoint. One- and two-step arithmetic — totals, differences, conversions, date math — looks reliable, but longer chains of dependent steps and aggregation across many table rows are hard for a one-pass model without a scratchpad; the company's advice is to have Clairic predict the value and let code do the math. Estimates need evidence in the input, calibration is measured rather than guaranteed (intervals can run narrow on unfamiliar data), and forecasting is basic — not a replacement for dedicated time-series models. The operational guidance: use the confidence scores, p_null, and the intervals to decide what to automate and what to route for human review.
And the name: Cloudflare kept the "cl" sound of Clef, nodded to Clair de Lune, and packed in the job description — a model for clerical tasks that extracts data clearly, with a prediction side leaning into clairvoyance. It also doubles, the company says, as shorthand for [Cl]oudflare's [AI R]egression model. Whether the category survives its early-checkpoint limits is now in developers' hands.
Frequently asked questions
What is Clairic?
Clairic is Cloudflare's "System One" extraction model, announced October 19, 2026 and available as a preview on Workers AI as @cf/cloudflare/clairic. It reads unstructured text and up to four images, then returns typed values — extracted, computed, estimated, or forecasted — in a single forward pass with no output tokens, so billing applies to input tokens only ($0.10 per million, per Cloudflare's docs). Cloudflare says it plans an open-weights release "soon," with no date given.
How is it different from an LLM?
LLMs generate open-ended text token by token; Clairic returns typed values: text spans with character offsets, numbers, dates, lists, estimates as distributions with a median and 80% interval, and forecasts. Every answer carries a confidence score and a p_null probability, and fields the input doesn't determine return null rather than hallucinated text. In Cloudflare's claims-pipeline test, a Clairic → Clef → GLM-5.3 cascade was 69% faster and 49% cheaper per million claims than an all-GLM-5.3 version.
What can't it do yet?
Cloudflare calls the endpoint an early checkpoint. Multi-step arithmetic beyond one or two dependent steps is unreliable (it advises doing the math in code), estimates need evidence in the input, interval calibration is measured rather than guaranteed, and forecasting is basic — not a replacement for dedicated time-series models. Its guidance: answers are guaranteed to be well formed, not necessarily correct, so use the confidence scores, p_null, and intervals to decide what to automate versus route for review.