Run a coding agent that never silently truncates: hands-on with UNCUT
UNCUT (Balanov/uncut, MIT, 388 GitHub stars) is a single static Go binary with four tools and no TUI, telemetry, or context compaction: it sends the full conversation on every model call and fails loudly instead of presenting a cut-off answer as success. This guide installs v0.1.1, runs it against a hosted OpenAI-compatible endpoint and a local Ollama model, pipes a diff through it, resumes a session, and reproduces its no-API-key lossless proof.
- Who: UNCUT, by Balanov on GitHub. A headless coding-agent harness written in Go — 837 lines of implementation Go, no third-party Go dependencies, MIT licence.
- What: One static binary, four tools (
read_file,write_file,replace,run_command), plain stdin/stdout, optional NDJSON events with--json, and append-only JSONL sessions. No TUI, telemetry, plugin system, background agents, automatic retries, or context compaction. - When: First released 1 November 2026 as v0.1.0; v0.1.1 followed the same day. At research time on 2 November 2026: 388 GitHub stars.
- Size and speed: About 7 MB per platform binary (the project measured 7,109,120 bytes on Windows and 6,901,920 bytes for a local Linux amd64 build). Its recorded median
--versionlaunch time was 9.461 ms on Windows 11 with warm caches, against 243.339 ms for Pi 1.4.0 in the same harness — a process-launch measurement, not a coding-speed claim. - Providers: OpenAI-compatible Chat Completions endpoints, including local servers. A local Ollama setup with
qwen3:8bwas smoke-tested by the project; no API key is required by default for local endpoints. Hosted use needs a model id and an API key. - Failure contract: Provider truncation (
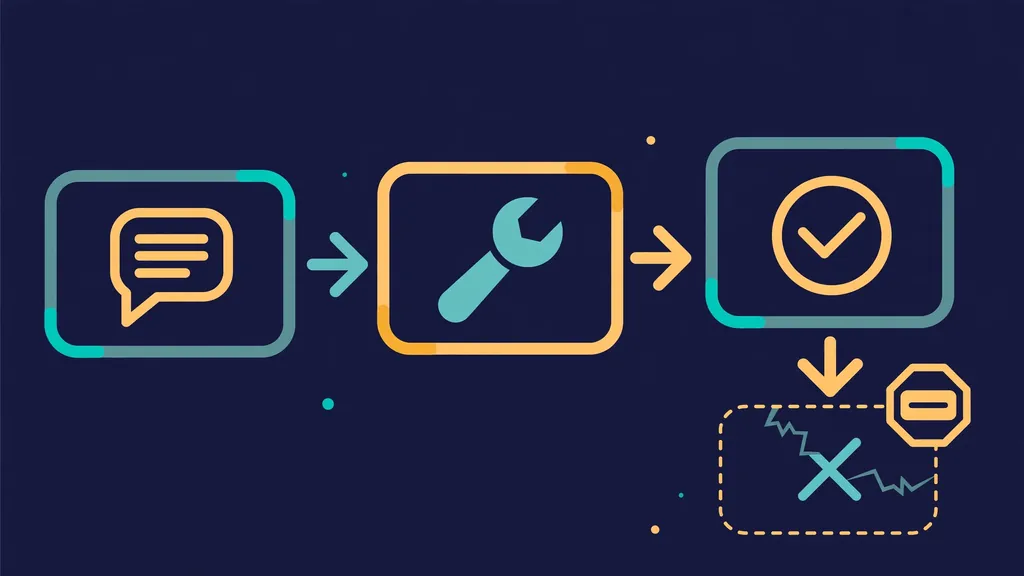
finish_reason=length) exits with code 3 and no partial stdout; reaching--max-steps(default 32) exits with code 4. Invalid UTF-8 is rejected explicitly, never silently replaced.
Why this matters now
Coding agents usually hide a trade-off: when a file is long, a log is huge, or a conversation grows, something gets summarised, pruned, or quietly cut so the next call fits. You rarely see what was lost, and the answer that comes back can look complete while resting on a partial view. UNCUT takes the opposite position, and it is small enough to audit: 837 lines of implementation Go, four tools, one provider protocol, one agent loop. It sends the entire conversation on every model call. File contents and combined command output are never truncated by UNCUT. If the provider cuts a response at its output limit, UNCUT exits with an error instead of presenting a partial answer as success.
That is a narrower promise than it first sounds, and the project says so itself. UNCUT does not extend a model's context window and cannot control provider-side processing. When the context or output limit is exceeded, the provider may reject or cut the response; UNCUT surfaces that failure instead of hiding it. It also deliberately leaves out almost everything a full agent product adds: no TUI, no telemetry, no plugin system, no background agents, no automatic retries, no context compaction, no sandbox. What you get is a predictable layer between an OpenAI-compatible model and a shell, suited to pipelines, CI jobs, containers, and agent experiments where the behaviour you most need is that nothing is silently dropped.
What you’ll need
- A Linux, macOS, or Windows machine (amd64 or arm64 builds are published for all three). The project requires Go 1.26 or later only if you build from source.
- A model to call: either an OpenAI-compatible hosted endpoint with an API key, or a local server such as Ollama with a tool-capable model installed. No API key is required by default for local endpoints.
- Python 3 if you want to run the lossless proof in Step 6. It needs no API key, model, or third-party package.
- A disposable workspace for the first real run. UNCUT is not a sandbox: the model can execute shell commands with your operating-system user's permissions, so do not point it at anything you cannot afford to change.
Step 1: Install the v0.1.1 binary and verify its checksum
Version 0.1.1, published 1 November 2026, is the current release. On Linux, download the binary for your architecture, put it on your PATH, and confirm it runs:
VERSION=0.1.1
ARCH=amd64  # Use arm64 on ARM64.
curl -fSLo uncut "https://github.com/Balanov/uncut/releases/download/v${VERSION}/uncut-linux-${ARCH}"
mkdir -p "$HOME/.local/bin"
install -m 0755 uncut "$HOME/.local/bin/uncut"
export PATH="$HOME/.local/bin:$PATH"
uncut --version
Every release includes a checksums.txt file. Verify the download before you run it, in the directory where you downloaded it:
VERSION=0.1.1
ARCH=amd64
curl -fSLO "https://github.com/Balanov/uncut/releases/download/v${VERSION}/checksums.txt"
grep "uncut-linux-${ARCH}$" checksums.txt | sha256sum -c -
On macOS, use uncut-darwin-${ARCH} (arm64 on Apple silicon, amd64 on Intel) with the same steps. On Windows PowerShell, the documented form downloads uncut-windows-$Arch.exe into $env:LOCALAPPDATA\Programs\UNCUT and adds that folder to $env:Path. The binaries are not code-signed yet, so SmartScreen or Gatekeeper may warn; verify the SHA-256 checksum first, and on macOS remove quarantine from that one file only with xattr -d com.apple.quarantine "$HOME/.local/bin/uncut". To build from source instead, with Go 1.26 or later:
go install github.com/Balanov/uncut/cmd/uncut@latestOr clone the repository and build the checkout with go build -trimpath -ldflags="-s -w" -o bin/uncut ./cmd/uncut (use bin/uncut.exe on Windows). Either way, uncut --version should print uncut 0.1.1.
Step 2: Point it at a model, then ask for a read-only explanation first
UNCUT reads three environment variables. UNCUT_MODEL is the model id, required unless you pass --model. UNCUT_BASE_URL is the OpenAI-compatible base URL, falling back to OPENAI_BASE_URL and then to the OpenAI default. UNCUT_API_KEY is the bearer token, falling back to OPENAI_API_KEY and then to no token. For a hosted OpenAI-compatible provider such as OpenRouter:
export UNCUT_API_KEY="YOUR_API_KEY"
export UNCUT_MODEL="your-model-id"
export UNCUT_BASE_URL="https://openrouter.ai/api/v1"
uncut "Inspect this repository and fix the failing tests"
Replace the model id with a real one for the provider you use; the README's examples are placeholders, not working model names. For a local model, the project documents an exact setup it smoke-tested with Ollama and qwen3:8b. Replace the model with one actually installed on your machine, because tool-call behaviour depends on the model:
ollama pull qwen3:8b
export UNCUT_BASE_URL="http://localhost:11434/v1"
export UNCUT_MODEL="qwen3:8b"
uncut "Explain this repository"
Start with a question that cannot change anything, and watch what the model reads. In PowerShell, set variables with $env:UNCUT_BASE_URL = "..." and $env:UNCUT_MODEL = "...". There are no approval popups, automatic commits, or hidden recovery loops: if the prompt asks for an edit, the model can make it through the file tools, and if it asks for a command, it can run it. Keep the first run in a copy of a repository, not the original.
Step 3: Pipe a diff or a log in, and tell it not to edit anything
UNCUT is built for Unix pipelines. Anything piped into stdin is appended to the prompt verbatim, and the tool accepts valid UTF-8 text while rejecting invalid input rather than replacing bytes silently. That makes it a natural reviewer for work you already have:
git diff | uncut "Review this diff. Do not edit files."
cat failing-test.log | uncut "Find the likely cause"
The four tools are the whole surface. read_file reads an entire UTF-8 text file. write_file writes complete file contents and creates parent directories. replace replaces exactly one occurrence; zero or multiple matches fail, so an edit cannot silently hit the wrong place. run_command returns the exit code and the complete combined stdout and stderr. File paths must stay inside the workspace, and run_command uses /bin/sh -c on Unix and cmd.exe /D /S /C on Windows. Remember the limit the project states plainly: workspace checks on the file tools do not constrain what a shell command can access, so a command can reach beyond the workspace. Run untrusted tasks in a disposable container or isolated environment, and review sessions and changes yourself.
One platform edge is worth knowing before you rely on piped output. Some Windows utilities emit UTF-16 or code-page output rather than UTF-8; UNCUT rejects that output instead of guessing a conversion, so configure commands to emit UTF-8 when possible. Binary files and invalid UTF-8 are likewise rejected explicitly. UNCUT uses non-streaming Chat Completions and supports text plus tool calls, not images.
Step 4: Get structured events with --json for scripts and CI
By default, only the final text goes to stdout, which keeps the output script-friendly. Add --json and UNCUT emits NDJSON events instead:
uncut --json "Run the tests and fix the failure"The event stream contains user, assistant, assistant_meta, tool, and finally done or error records. Assistant messages include complete tool calls, tool messages include complete results, and usage and finish reasons arrive as separate assistant_meta events. Nothing in that stream is a summary of a longer result: the design is that a script consuming the events sees the same complete messages the model saw. In a CI job, that also means a failure is machine-readable — an error event and a non-zero exit code, rather than a plausible-looking partial answer on stdout.
Step 5: Resume a session, use AGENTS.md, and set explicit guards
A session is an append-only JSONL file. If the file exists, UNCUT resumes its complete history; new messages are appended and synced after each step. Invalid or partial records cause an explicit error and are never discarded to make a session load:
uncut --session .uncut/work.jsonl "Start the refactor"
uncut --session .uncut/work.jsonl "Continue with the tests"
Session files can contain source code, command output, and secrets, so store them accordingly and keep them out of version control. By default, UNCUT also reads AGENTS.md in full from the workspace root and adds it to the system prompt; pass --no-agents to skip it. On a resumed session, the original stored system message is reused, so changing AGENTS.md mid-session does not silently change the instructions the resumed run is operating under. Useful flags, with their defaults, are --cwd (the workspace for file tools and shell commands, defaulting to the current directory), --session, --max-steps (32), --max-tokens (the provider default), --request-timeout (10 minutes per request; 0 disables it), --no-agents, --json, and --version.
Set the guards deliberately for unattended runs. A low --max-steps bounds how many model calls a run can make before it exits with code 4, and an explicit --max-tokens sets the provider output limit instead of leaving it to the provider default. Those are the only brakes UNCUT offers — there is no approval step, no retry loop, and no compaction to rescue a run that is drifting. If a run needs to stop, it stops with an exit code you can act on, which is the next step's subject.
Step 6: Run the lossless proof yourself, with no API key
The most useful thing about UNCUT may be that its central claim is checkable without a model. The repository ships a proof script that drives the real binary against a deterministic local provider on a loopback port. Clone the repository, build it, and run the proof:
git clone https://github.com/Balanov/uncut.git
cd uncut
go build -o bin/uncut ./cmd/uncut
python bench/proof.py ./bin/uncut
It needs Python 3, but no API key, model, or third-party package. It checks complete large-file and command-output transport, exact session resume, edits, explicit truncation failures, step limits, and invalid UTF-8 handling. The recorded results, in BENCHMARKS.md, are that all 442,400 bytes of a large UTF-8 file and piped prompt arrived unchanged (with the third request resuming the exact full history), all 213,018 bytes of combined stdout and stderr arrived unchanged, a provider truncation produced exit code 3 with zero bytes of partial stdout, two model calls with --max-steps=2 produced exit code 4, and invalid UTF-8 was rejected with no replacement characters substituted. Read those numbers as transport tests, not model-quality benchmarks: they prove what UNCUT passes through and how it fails, not whether a provider preserves context internally or produces a correct answer.
The same discipline applies to the project's startup measurements. A separate driver, bench/startup.py, measured 100 --version launches per CLI after five warmups, interleaving candidates. On the recorded Windows 11 machine, UNCUT's median was 9.461 ms and Pi 1.4.0's was 243.339 ms, with footprints of 7,109,120 bytes for the UNCUT executable against 112,329,741 bytes for Pi's full local installation tree. The project is explicit that this is a warm-cache CLI launch measurement that does not measure provider latency, token use, model quality, or the time to complete a coding task — and that Pi provides a substantially broader feature set. Reproduce it with the commands in bench/README.md before repeating any of it as a comparison.
What you built, and where it stops
You now have a coding-agent harness you can read in an afternoon, install as one binary, drive from a pipeline, and verify without spending a cent on model calls. In exchange for that smallness, you give up the safety nets: no sandbox, no approvals, no retries, no compaction, and no help when the full conversation no longer fits the model's context. That trade is the point. If your work needs a harness that never quietly drops context and tells you loudly when it cannot deliver, UNCUT is a credible, checkable choice. If your work needs guardrails around untrusted code, approval before edits, or long sessions that must survive context limits, this is not the tool — and its own documentation will tell you the same.
Frequently asked questions
Does UNCUT make a model smarter, or give it a bigger context window?
No. UNCUT does not extend a model's context window and cannot control provider-side processing. It sends the full conversation on every call and surfaces provider rejections or cut-offs as errors, but a conversation that no longer fits still fails rather than being silently compacted.
Is it safe to let UNCUT run commands on my machine?
Not by itself. UNCUT is not a sandbox: the model can execute shell commands with your operating-system user's permissions, and workspace checks on the file tools do not constrain shell commands. Run untrusted tasks in a disposable container or isolated environment, and review sessions and changes yourself.
Do I need an API key to try it?
No, not for the proof or for a local model. The lossless proof needs only Python 3 and no API key or model, and local endpoints such as Ollama need no API key by default. A hosted OpenAI-compatible endpoint needs a model id and an API key.