Soup hands-on: fine-tune an LLM from a single YAML file, from first config to a working adapter
Fine-tuning a language model is a solved pattern buried in friction: a training script here, a config format there, a separate tool for data, evaluation, and export. Soup collapses that stack into one YAML file and one command — and this guide takes it from first install to a working adapter, every command verified.
- Who: Soup (MakazhanAlpamys/Soup, Apache-2.0), a CLI for fine-tuning and post-training LLMs from one YAML file.
- What: one-command SFT/DPO/GRPO training, data tools, eval gating, merge, export, and push — plus beta layer streaming that trains an 8B model on a 4 GB GPU.
- When: verified October 30, 2026: soup v0.77.1, Python 3.12.3, torch CPU stack, Qwen2.5-0.5B-Instruct, 2-core CPU-only sandbox.
- Requirement: Python 3.11–3.13, about 2 GB for the training stack plus ~1 GB for the demo model. No account, no API key for local training; a GPU is recommended, CPU is experimental.
Why this matters now
Fine-tuning a language model has a reputation problem. The training itself is a solved pattern — pick a base model, show it examples, save the adapter — but everything around it is friction: a training script here, a config format there, a separate tool for data cleaning, another for evaluation, and a third for exporting the result somewhere useful. Soup exists to collapse that stack into one command-line tool driven by one YAML file, and it is climbing fast because of it. On October 30, 2026, the project — MakazhanAlpamys/Soup, Apache-2.0 — held 9,824 stars and 1,620 forks, had just shipped version 0.77.1, and was gaining roughly 238 stars a week on independent tracker counts. Its headline feature is the reason for the spike: layer streaming, a technique that trains an 8-billion-parameter model on a 4 GB laptop GPU by keeping the frozen base weights in host RAM and feeding them to the GPU one decoder layer at a time.
The numbers behind that claim are the project's own, measured and published in its benchmarks directory rather than asserted in marketing copy — and they deserve the same careful reading the project itself gives them. On an RTX 3050 Laptop with 4 GB, Llama-3.1-8B-Instruct with NF4 quantization ran at 119.6 tokens per second with a 3.32 GB peak on version 0.72.2, and a later post-repair run on another 4 GB laptop read 208.6 tokens per second in a 2.40 GB peak. Those are not figures this guide re-measures: the sandbox used here has no GPU at all, so the streaming numbers below are attributed to the project, and the guide points you at the project's own free Colab check — a T4 capped to 4 GB that asserts a streamed model is bit-identical to a normal one — if you want to verify them yourself. What this guide does verify, end to end, is the workflow every reader actually runs first: install, configure, train a real adapter, and generate from it. The training run below was executed on a 2-core CPU-only machine with 7.7 GB of RAM, which Soup documents as experimental and very slow. If it works there, it works on your laptop; on a GPU the same config runs the same way, faster, and with quantization switched on.
What you'll need
- Python 3.11, 3.12, or 3.13. Those are the versions Soup's CI tests; 3.14 is not supported yet because the PyTorch stack has not been validated there. This guide ran on Python 3.12.3.
- A virtual environment and about 2 GB of disk for the training stack, plus room for the base model. The light CLI alone is small; the
[train]extra pulls in PyTorch, transformers, PEFT, TRL, and datasets. The 0.5-billion-parameter model trained below downloads roughly 1 GB. - No account and no API key for local training. Everything here runs against models downloaded from the Hugging Face Hub. One exception to plan around: Soup's own chat template defaults to Llama-3.1-8B-Instruct, which is a gated model — you need Hugging Face access approval before it downloads. This guide trains Qwen2.5-0.5B-Instruct instead, which downloads without approval, and says so wherever the template default would send you to a gated download.
- A GPU is recommended; a CPU is the fallback, not the plan. Soup's README is blunt: CPU training is experimental and very slow, and quantization is auto-disabled on CPU. The CPU run below is deliberately tiny — 10 examples, 20 epochs — so it finishes in minutes. Treat it as proof the pipeline works, then scale the same config up on a GPU.
- About 30 minutes, most of it downloads. The commands themselves take seconds except the training run and the model download.
Step 1 — Install Soup and check your machine
Install the light CLI first, then add the training stack into the same environment. The light install is enough for configuration, data tools, and inspection; the README states that fine-tuning (soup train) needs the [train] extra.
python3 -m venv .venv
source .venv/bin/activate
pip install soup-cli
pip install "soup-cli[train]"
soup --version
Expected output, verified October 30, 2026:
soup v0.77.1
https://github.com/MakazhanAlpamys/Soup
Note the double quotes around "soup-cli[train]" — Soup's README stresses this spelling because it is the only one that works in every shell, and single quotes will make pip reject the extra on some systems. Then run the doctor command, which reports Python, GPU backend, RAM, disk, and every dependency in one table:
soup doctorOn the CPU-only sandbox, doctor reported Python 3.12.3, Linux x86_64, a GPU backend of "unknown (torch not installed)" before the training extra was added, 8 GB of RAM, and 43 GB of free disk, with the light dependencies (pydantic, typer, rich, pyyaml, plotext) all marked OK and torch listed under [train] as not installed. After the training install, doctor reported a "CPU only" backend with the warning "Training will be slow without GPU," torch 2.15.0+cpu, transformers 5.22.1, peft 0.21.2, trl 0.29.1, datasets 5.1.0, and the verdict "All checks passed! Your environment is ready." If doctor flags a missing item, fix that item before going further — every later step assumes this table is green.
Step 2 — Let quickstart show you the shape of a run
Before writing your own config, generate Soup's demo and read it. The dry-run flag creates the demo data and config without training anything:
mkdir soup-demo && cd soup-demo
soup quickstart --dry-run --output . --yes
That writes two files. quickstart_data.jsonl holds 20 examples in Alpaca format — each line an instruction, an input, and an output — and quickstart_soup.yaml is the whole training job:
# Soup Quickstart Config — auto-generated demo
base: TinyLlama/TinyLlama-1.1B-Chat-v1.0

task: sft

data:
  train: ./quickstart_data.jsonl
  format: alpaca
  val_split: 0.1

training:
  epochs: 1
  lr: 2e-4
  batch_size: auto
  lora:
    r: 16
    alpha: 32
  quantization: "none"

output: ./quickstart_output
Every field earns its place. base is the model to adapt. task: sft selects supervised fine-tuning from Soup's 23 methods, which also include DPO, ORPO, SimPO, KTO, and GRPO. data.format: alpaca tells Soup how to read your JSONL; val_split: 0.1 holds back a tenth of the rows for validation. Under training, lora.r and lora.alpha size the adapter — rank 16 with alpha 32 is the demo's modest default — and quantization: "none" is what a CPU run wants, since Soup disables quantization on CPU anyway. Inspect the demo data with Soup's own tool rather than eyeballing it:
soup data inspect quickstart_data.jsonlVerified output: 20 samples, columns instruction, input, output, average length 96 characters, minimum 73, maximum 112, zero empty fields, zero duplicates. That is the standard to hold your own data to in the next step.
Step 3 — Write your own dataset and config
The demo teaches general knowledge. A better test of whether training worked is a dataset with a visible format: every answer is one sentence, then one line starting with "Example:". Ten examples are enough to teach a format — not enough to teach facts, and this guide does not pretend otherwise. Create data.jsonl:
{"instruction": "What is photosynthesis?", "input": "", "output": "Photosynthesis is how plants turn sunlight, water, and carbon dioxide into food and oxygen.\nExample: A sunflower uses photosynthesis to grow toward the light."}
{"instruction": "What is inflation?", "input": "", "output": "Inflation is a rise in prices that lowers what a unit of money can buy.\nExample: A loaf of bread that cost two dollars last year costs two dollars and twenty cents this year."}
{"instruction": "What is recursion?", "input": "", "output": "Recursion is when a function solves a problem by calling itself on a smaller version of it.\nExample: A countdown function prints a number, then calls itself with the next lower number."}
{"instruction": "What is a black hole?", "input": "", "output": "A black hole is a region of space where gravity is so strong that nothing, not even light, can escape.\nExample: A star much heavier than the Sun can collapse into a black hole at the end of its life."}
{"instruction": "What is an algorithm?", "input": "", "output": "An algorithm is a step-by-step procedure for solving a problem or completing a task.\nExample: A recipe is an algorithm for cooking a meal."}
{"instruction": "What is evaporation?", "input": "", "output": "Evaporation is when a liquid changes into a gas at its surface.\nExample: A puddle shrinks on a sunny day because its water evaporates into the air."}
{"instruction": "What is a budget?", "input": "", "output": "A budget is a plan that assigns expected income to expected spending over a set period.\nExample: A student budgets fifty dollars a week for groceries and ten for transport."}
{"instruction": "What is friction?", "input": "", "output": "Friction is the force that resists motion between two surfaces in contact.\nExample: Rubbing your hands together warms them because of friction."}
{"instruction": "What is a vaccine?", "input": "", "output": "A vaccine is a preparation that trains the immune system to recognize a pathogen without causing the disease.\nExample: A flu vaccine teaches the body to recognize influenza viruses before winter."}
{"instruction": "What is the water cycle?", "input": "", "output": "The water cycle is the continuous movement of water between the Earth and the atmosphere through evaporation, condensation, and precipitation.\nExample: Ocean water evaporates, forms clouds, and falls back as rain."}
Then the config, soup.yaml. It mirrors the quickstart file with three deliberate changes: a smaller, ungated base model so the download needs no approval; max_length: 256 so short examples do not pad out to long sequences on a slow CPU; and 20 epochs. Twenty epochs on ten examples sounds like a lot, and it is deliberate: the first run of this guide used 2 epochs — 6 optimizer steps — and the resulting adapter changed almost nothing, not even on a question it had trained on. Small data needs many passes before the format sticks, and this guide verified that 20 epochs is where the effect appears:
base: Qwen/Qwen2.5-0.5B-Instruct

task: sft

data:
  train: ./data.jsonl
  format: alpaca
  val_split: 0.1
  max_length: 256

training:
  epochs: 20
  lr: 2e-4
  batch_size: auto
  lora:
    r: 16
    alpha: 32
  quantization: "none"

output: ./output
Validate before you spend any compute. The dry-run flag checks the config and the data without training, and it is also the fastest way to catch Soup's strictest new behaviour: since version 0.75, unknown config keys are rejected instead of silently ignored, so a typo like quantizaton fails here rather than quietly doing nothing during a long run:
soup train --config soup.yaml --dry-runVerified output on the CPU-only sandbox:
Loading config from soup.yaml...
Device:  CPU (no GPU detected)
Memory:  N/A (CPU mode)
Model:   Qwen/Qwen2.5-0.5B-Instruct
Task:    sft
Backend: transformers
LoRA:    r=16, alpha=32
Quant:   none
Seed:    42 (unset default)
Dry run - validating data...
Data OK: 9 train samples
Val: 1 samples
Config valid. Ready to train!
While you are here, ask Soup what the run will cost in memory before it starts. soup profile estimates memory, speed, and GPU requirements from the same config, using one peak-VRAM estimate calibrated on 39 measured runs in version 0.77:
soup profile --config soup.yamlVerified output for the same config:
Model:     Qwen/Qwen2.5-0.5B-Instruct
Params:    0.5B (trainable: 1,081,344 with LoRA r=16 on q_proj, v_proj)
Quantization: none

GPU Memory Estimate:
  Model                                 ~1.0 GB
  LoRA                                  ~0.0 GB
  Optimizer                             ~0.0 GB
  Activations (bs=4, seq=256)           ~1.2 GB
  Logits and loss (vocab 151,936)       ~1.9 GB
  Overhead                              ~0.7 GB
  --------------------               ----------
  Total                                 ~4.8 GB

Speed Estimate:
  Tokens/sec: ~2,500
  Samples/sec: ~9.8
  Typical A100 throughput, not specific to your GPU.

Recommendations:
  ? No GPU detected: would fit in an assumed 24 GB (need ~5 GB).
  ? batch_size 8 assumes 24 GB VRAM

Compatible GPUs:
  - RTX3050_6GB (6 GB)
  - RTX3050LAPTOP_6GB (6 GB)
  - RTX3060LAPTOP (6 GB)
  - RTX4050LAPTOP (6 GB)
  - RTX3050 (8 GB)
Read that estimate the way it is labelled. The memory total is the useful number — about 4.8 GB, which is why even a 6 GB laptop card appears on the compatible list. The speed line is explicitly "typical A100 throughput, not specific to your GPU," so do not plan a CPU run around 2,500 tokens per second; the CPU run in the next step is far slower, and that is expected.
Step 4 — Train the adapter
Run it. The first launch downloads the base model (roughly 1 GB for Qwen2.5-0.5B-Instruct) and then trains. The --yes flag skips the start-training confirmation; it is required when stdin is not a terminal (scripts, CI, pipes), and harmless interactively:
soup train --config soup.yaml --yesVerified run on the CPU-only sandbox (base model already cached; first launch downloads roughly 1 GB): 60 steps over 20 epochs in 374 seconds of training time, about 7 minutes wall-clock, ending at train loss 0.7489 against 1.806 for the 2-epoch run. Final validation loss was 1.377 — treat that number loosely, because with val_split: 0.1 on ten examples the validation set is a single row, so it swings from epoch to epoch. The finished adapter directory contains adapter_config.json (rank 16, alpha 32, target modules q_proj and v_proj, base Qwen/Qwen2.5-0.5B-Instruct), adapter_model.safetensors (4,338,000 bytes), the ChatML chat template, and the tokenizer files — plus a checkpoint-60 directory. The adapter is small by design: LoRA trains only about 1.08 million parameters here, so the output is megabytes, not another copy of the base model. If the run dies with an out-of-memory error on a CPU box, the honest fixes are a smaller base model, a shorter max_length, or a smaller LoRA rank — not a bigger swap file.
Step 5 — Prove the adapter did something
A finished adapter directory is not proof of learning; a changed answer is. Run batch inference over a held-out question — one the model never saw in training — with the adapter loaded, and compare it against the base model answering the same prompt. One gotcha first, learned the hard way in this guide's verification: soup infer treats each prompt as plain text. Feed it a bare question and you get plain completion from both models, adapter or not. For a chat model, wrap the question in the model's ChatML turns — the same template Soup saved into the adapter directory — so generation starts in the assistant turn where training happened:
python3 - <<'EOF'
import json
p = "<|im_start|>system\nYou are Qwen, created by Alibaba Cloud. You are a helpful assistant.<|im_end|>\n<|im_start|>user\nWhat is an API?<|im_end|>\n<|im_start|>assistant\n"
open('prompts-chat.jsonl','w').write(json.dumps({"prompt": p})+"\n")
EOF
soup infer --model ./output --input prompts-chat.jsonl --output results.jsonl --temperature 0
soup infer --model Qwen/Qwen2.5-0.5B-Instruct --input prompts-chat.jsonl --output results-base.jsonl --temperature 0
Verified outputs on the CPU-only sandbox, temperature 0 (greedy decoding, so no sampling luck in the comparison). The base model answered with 220 tokens of essay:
An API (Application Programming Interface) is a set of rules and protocols that allow different software applications to communicate with each other. It's like a bridge between different systems or services, enabling them to exchange data and perform tasks.

APIs are designed to be flexible and reusable, allowing developers to create custom solutions without having to write code from scratch for every interaction they need to have. [...]
The adapter answered the identical prompt in 54 tokens — and in exactly the trained shape:
An API stands for "as a service". It's a way for developers to build applications that don't need to know about the underlying technology or infrastructure.
Example: A web developer can use an API to create a website without knowing how it works under the hood.
Read that result honestly, because it teaches two things at once. The format transferred perfectly: one sentence, then an "Example:" line, on a question the model never trained on. The facts did not: "stands for 'as a service'" is muddled, and the sentence is vague. Ten examples cannot teach a model new facts, and the guide does not claim they do — what they teach is the two-part answer shape, and the held-out answer above shows that shape surviving on an unseen question. That is the correct mental model for small fine-tunes generally: format and style transfer first, knowledge second, and only with far more data. Temperature 0 matters here: it removes sampling luck from the comparison, so the format match is evidence, not a coin flip.
Step 6 — Ship the adapter as a full model
An adapter is only useful with its base model attached. Merge the two into a standalone model directory, which you can then serve, export, or upload:
soup merge --adapter ./output --output ./mergedVerified on the CPU-only sandbox in 35 seconds: Soup printed a merge plan (adapter ./output, base Qwen/Qwen2.5-0.5B-Instruct, float16 output), loaded the base weights and the adapter, and wrote a standalone model of 953.2 MB — model.safetensors plus config.json, generation_config.json, the chat template, and the tokenizer files. The merged directory answers without any adapter flag, which is the point: it is now just a model.
From there, the same CLI covers the rest of the lifecycle without new tools: soup chat --model ./merged for an interactive session, soup export --model ./merged --format gguf --quant q4_k_m for a GGUF file that Ollama or llama.cpp can serve, and soup push --model ./merged --repo you/my-model to publish to the Hugging Face Hub — the last one needs a Hub token and is the only step in this guide that touches an account. The template config in Step 2's soup init --template chat is the same file shape scaled up: Llama-3.1-8B-Instruct, 4-bit quantization, LoRA rank 64, 3 epochs. Swap your base, data, and output paths into it and the workflow does not change.
Step 7 — The trick behind the headline: layer streaming
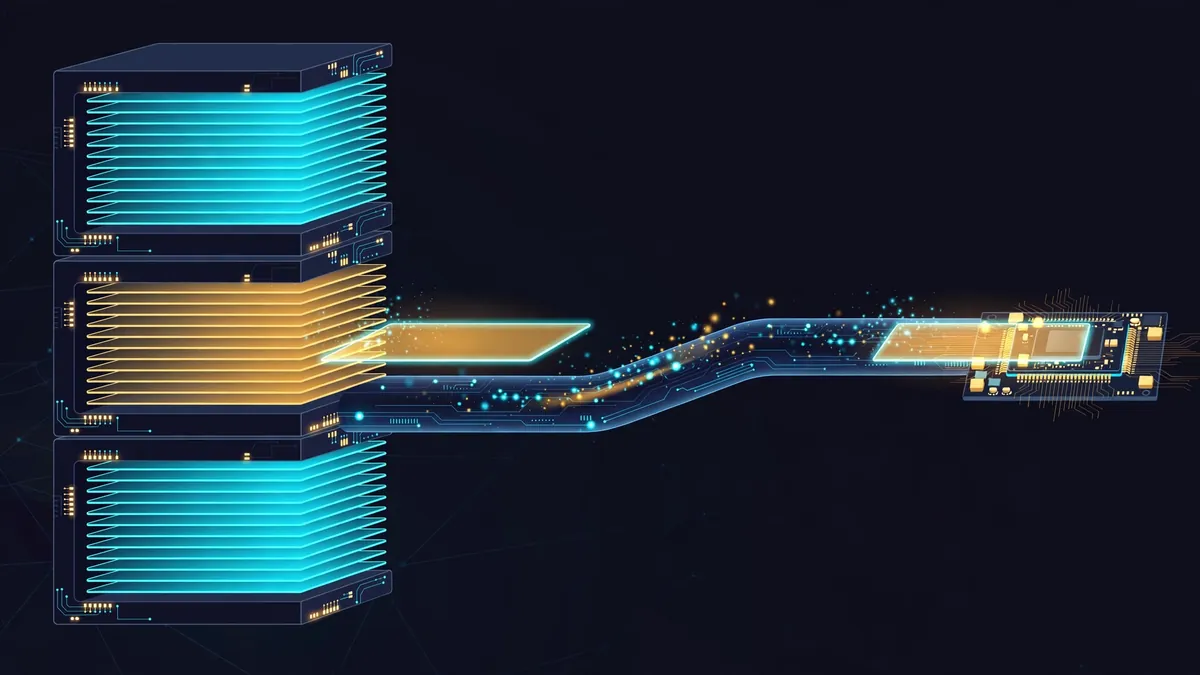
Everything so far works on any GPU with room for the model. Layer streaming is for the machine that does not have room. Normally, fine-tuning keeps the whole frozen base model in VRAM; on a 4 GB card, an 8-billion-parameter model does not fit even quantized, so training is simply unavailable. Streaming changes what "fits" means: the frozen base lives in host RAM (or NVMe), and Soup copies it to the GPU one decoder layer at a time on a dedicated CUDA stream. Peak VRAM is bounded by one layer plus the adapter, not by the model — hence the project's measured 3.32 GB peak for an 8B model on a 4 GB card.
Three honest caveats come with it, all from the project's own record. First, streaming is beta and opt-in: add stream_layers: true to the training section of your config, and expect slower wall-clock time than a resident run, because layers shuttle back and forth. Second, the measurement history is unusually transparent, including a retraction: version 3 of the layer-streaming preprint withdraws its earlier explanation that streaming is bound by host-to-device transfer, after measuring that deleting every host-to-device byte buys only 1.4% — the real streaming cost is per-layer NF4 dequantisation, about 9.8% of the step. Third, the project once shipped a silent wrong-gradient defect on NF4 layers above about 165 MiB, where the forward pass stayed bit-exact and the loss curve looked healthy while gradients were wrong; it was found, reported upstream, and repaired, with the repair gated against controls on real 32B and 72B models. None of that makes streaming unusable — it makes it a beta feature to enable deliberately, on a card that needs it, with the project's Colab T4 self-check as your own verification before trusting it on a real run.
When to use Soup vs the alternatives
Soup is not the only way to fine-tune, and the alternatives are not straw men. LLaMA-Factory covers a similar breadth with a web UI and a larger recipe collection, and it is the better pick if you want to click through configuration. Axolotl gives you deeper config control and a long track record on multi-GPU setups, at the cost of more YAML to learn. Unsloth is the speed pick on supported GPUs, with 2–5× faster training claimed for its kernels — Soup itself offers it as a backend option (backend: unsloth with the [fast] extra) rather than competing with it. Raw Hugging Face Trainer is still the right choice when you need full control over the training loop itself. Choose Soup when you want one CLI for the whole arc — data tools, method selection, eval gating, merge, export, and push — with a config file you can read in a minute, and when your hardware is the constraint: its memory estimates, quantization menu, and layer streaming are built for small cards first.
Limits and gotchas, collected in one place
- CPU training is a smoke test, not a strategy. Soup says so itself: experimental and very slow. The 10-example run here exists to prove the pipeline; real datasets belong on a GPU or on Apple Silicon via the MLX backend.
- Configs are strict since 0.75. Unknown keys fail the load. Run
soup doctor --config soup.yamlafter upgrading from 0.76, and runsoup train --dry-runbefore any long job. - The chat template's default model is gated.
soup init --template chatwrites Llama-3.1-8B-Instruct as the base. If you have not been granted access on the Hugging Face Hub, the download fails with an authorization error — swap in an ungated model first, as this guide does. - Quantization is auto-disabled on CPU. Do not be surprised when a CPU run ignores
quantization: 4bit; that is documented behaviour, not a bug, and it is why the CPU config here says"none"explicitly. - Layer streaming is beta and opt-in. It trades speed for fit. On a card with room to spare, a resident run is faster; streaming earns its keep on 4–8 GB cards.
- Version churn is real. Version 0.77.0 alone refused configs 0.76 merely warned about, and the project ships 183 releases. Pin the version you verified —
soup-cli==0.77.1here — in any config you intend to rerun months later.
The takeaway
Soup's idea is deliberately boring: one file describes the job, one command runs it, and the same command covers data, training, evaluation, merging, and shipping. The interesting part is what that boring idea unlocks on modest hardware — a real adapter trained on your own examples, in an afternoon, on a machine that was never supposed to train models at all, and on a 4 GB laptop GPU, an 8-billion-parameter model that previously did not fit. Start with the CPU smoke run above to learn the shape of the workflow, then take the same YAML to a GPU, switch quantization back on, and point it at a dataset that actually matters to you. The config will not need to change shape — only scale.
Sources: the Soup README and repository page (install routes, quickstart, configuration fields, layer-streaming measurements, requirements, version 0.77.1 release notes, read October 30, 2026), the v0.77.0 release notes (config strictness, MLX GRPO, layer streaming for DeepSeek-V3), and the verification runs quoted in Steps 1–6 (doctor output, quickstart files, data-inspect stats, dry-run validation, training run, inference comparison, merge). The 8B-on-4GB figures (3.32 GB peak, 119.6 tok/s pre-repair; 2.40 GB peak, 208.6 tok/s post-repair) are the project's measured figures, not independent measurements — this sandbox has no GPU. The template default model Llama-3.1-8B-Instruct is gated on the Hugging Face Hub; the guide trains an ungated model instead.