Every morning the AI industry publishes a thousand stories and maybe ten that matter. Feed readers hand you the thousand; AIHOT hands you the ten. AIHOT (KKKKhazix/AIHOT, MIT) is a self-hosted website framework that finds its own hot topics and writes its own daily digest: it pulls from six source types, has an LLM pre-screen and then independently score every candidate twice, clusters coverage of the same event, ranks by heat, and publishes a daily edition — the same engine running the live site aihot.news. It went from zero to nearly 6,700 GitHub stars in under two weeks. This walkthrough boots your own instance in about half an hour and shows you how to turn it into a hotspot site for your industry.
The design is the whole pitch: AIHOT treats source curation as a knowledge-management problem. Six source types — RSS, web lists, JSON APIs, X accounts, WeChat public accounts, and content pushed in by your own scripts — are split into three tiers (official first-party, official accounts and quasi-official, media and individuals), each with its own admission threshold, and scrape frequency adjusts automatically with output. A story that survives pre-screening gets scored twice against the same rubric, gets a rewritten title and summary, and is clustered with other coverage of the same event: an LLM decides whether two stories are the same story, a follow-up, or two different things, with a second model able to re-review the decision (GROUP_REVIEW_MODEL). Heat is computed per event, not per article: each independent source counts once inside a 48-hour window, halving after 24 hours, so one outlet publishing ten takes on the same story does not move the needle — what ranks is what a lot of people are actually talking about.
docker compose file.git clone https://github.com/KKKKhazix/AIHOT.git myhot
cd myhot
node scripts/init-env.ts --llm-key <your-model-api-key>init-env writes your .env from a template, configured for DeepSeek by default. If you want Qwen, Zhipu, or another OpenAI-compatible provider, the .env.example file shows exactly which three values to change (LLM_BASE_URL, LLM_MODEL, LLM_EXTRA_JSON). Using a reasoning model that thinks before answering? Also set LLM_REASONING_TOKENS so the reasoning pass does not eat the output budget. The repo ships as a template, so the author suggests clicking Use this template and cloning your own copy if you plan to keep it; a straight clone is fine for a first try.
docker compose up -d --buildOpen http://localhost:3000. The admin panel lives at /admin — the password is the ADMIN_PASSWORD init-env put in your .env. Within a couple of minutes the site starts filling with content, processed from the 18 public overseas AI news sources bundled as demos. The README warns you not to mistake these for the real thing: the repository deliberately ships without the live site’s source list and operating data — the demo feeds exist so you can see the pipeline working before you rewire it.
In the admin panel you can manage sources, trial a scrape, and inspect the diagnostics of every pipeline step. Here is what each item goes through, in the README’s own order:
site/site.ts under EDITION_TIMES.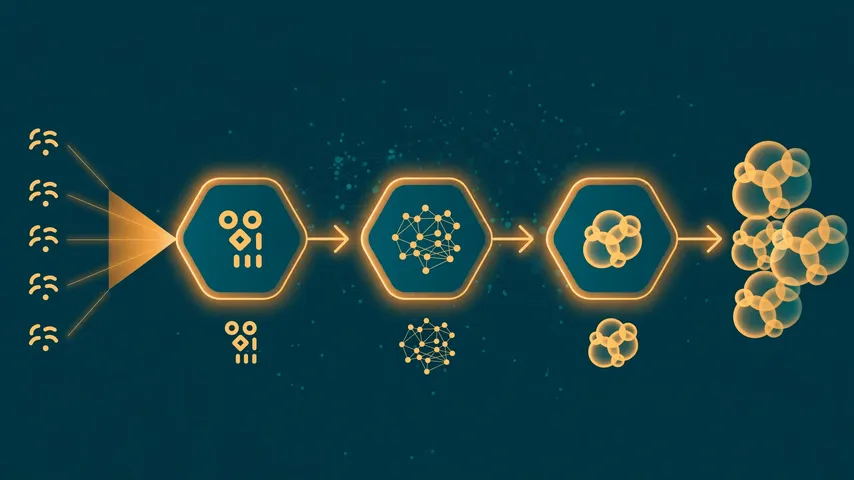
This is the part the author — a designer who rebuilt the codebase with AI half a year after picking it up, and open-sourced it because lawyers, HR people, and finance folks kept asking for their own industry version — actually designed for. Nearly everything lives in two folders, site/ and industry/, and the knowledge-heavy pieces are plain Markdown you can edit without touching code:
site/site.ts — site name, industry vocabulary, edition times, homepage copy, about page, and the categories your public API exposes.industry/taxonomy.ts and industry/topics.json — categories, tags, and topic pages.industry/sources.json — the sources imported on first boot. Replace the demo feeds with your industry’s.industry/prompts/ — every prompt in the pipeline, verbatim. Your industry know-how goes here.industry/selection.ts — the admission thresholds.The author’s recommended shortcut is to hand the whole repo to a coding agent (Claude Code or Codex) with this instruction:
Please read AGENTS.md and docs/customize.md, and turn this site into a hotspot site for the [YOUR INDUSTRY] industry.
I care about: ... (the sources you want to watch, what counts as hot for you, what doesn't — be specific).
When done, run npm run typecheck, npm test and node scripts/smoke.ts, and tell me what decisions are left for me.
The most valuable thing to get right is the scoring rubric (industry/prompts/selection-score.md) and the thresholds: label a couple hundred items yourself, run scripts/eval-selection.ts to see how well the current settings match your judgment, and iterate. The docs folder has a full calibration guide (docs/: sources, selection and calibration, event grouping, digest evaluation, deployment, architecture).
Your own hotspot news site: an ingestion engine over six source types, a double-scored LLM curation pipeline with fully public prompts and thresholds, event clustering with cross-source heat ranking, and daily, weekly, and monthly digests — plus the same content exposed for machines: RSS (curated, all, full-text, digests), a public API, an MCP endpoint, /api/v1/agent, an openapi-v1.json spec, and llms.txt. One stack, one site, readable by people and agents alike.
README.en.md exists, but the project’s discussions, issues, and freshest docs are in Chinese. Budget some translation time if you do not read it.industry/sources.json with your own industry’s feeds, you have someone else’s demo, not your site.Still: the gap between “I follow the AI industry” and “I run the hotspot site my industry reads every morning” used to be a full newsroom. AIHOT closes it to a config file, a rubric, and a Docker command. That is worth an afternoon.