Stop trusting AI summaries: dig to the original sources with imozuru
A model summary tells you what a field supposedly says. imozuru makes you read what it actually says: it follows citations to the original sources, saves them without summarising, and machine-checks every extract. This guide installs it, runs its own verification on the bundled demo, and names exactly what it could not run.
- Who: imozuru (MaryCache/imozuru on GitHub), MIT license, 1,369 stars and 65 forks on October 29, 2026, created October 13, 2026; version 2.2.0 released October 28, 2026.
- What: a Claude Code / Codex skill that digs into an unfamiliar field by following citations, links, and authors to original sources, saving them verbatim and machine-checking extracts, with a dashboard for every investigation.
- When: verified October 29, 2026, on Python 3.12.3, against the cloned repository (README.en, SKILL.md, ten scripts, eleven tests, bundled demo).
- Requirement: Git and Python 3.10+ for everything verified here. The full agent path needs a Claude Code plan or Codex API billing; no GPU, no API key for the verified steps.
Why a no-summary research skill, and why now
Ask a capable model to "look into" an unfamiliar field and you get a familiar failure mode: a confident summary built from the top few search results, with the details you actually need for your own judgement quietly dropped. You cannot tell which claims rest on an original source and which rest on somebody else's retelling, because the summary has already flattened the difference. imozuru exists to refuse that trade. It is a Claude Code skill that digs into a field you do not know yet, pulls one lead after another — the Japanese idiom imozuru-shiki, like sweet potatoes coming up on a single vine — until it reaches original sources, and saves those sources without summarising them. You read the sources; the agent only points at the file and the lines.
The numbers explain the attention. imozuru (MaryCache/imozuru on GitHub, MIT license) was created on October 13, 2026, and a trending tracker recorded 1,173 new stars in its first stretch on the week's trending list; the GitHub API on October 29, 2026, shows 1,369 stars and 65 forks. Version 2.2.0 landed on October 28, 2026, adding Codex CLI instructions and a fix for a machine-checking bug in which extracts that dropped a leading minus sign passed verification. A sixteen-day-old skill shipping a 2.2.0 with a changelog that corrects its own verification logic is exactly the kind of project worth trying before it hardens into received wisdom — including the parts that are still rough, which this guide names plainly.
The method behind it comes from library and information science, not from prompt folklore. The README names three sources: Bates's berrypicking (1989), in which a searcher gathers information bit by bit as the question itself changes; Ellis's model of information-seeking behaviour; and Kuhlthau's Information Search Process. The practical translation is two rules. First, during the investigation, do not summarise: an early summary causes premature closure, locking in a conclusion before the search has found the counter-evidence. Second, decide when to stop by evidence, not by confidence: stop when every research point has an original source attached, or when following further leads turns up nothing new. Those two rules are the whole pitch, and they are testable in a way most agent skills are not — because the skill ships scripts that machine-check its own output, and this guide runs them.
What you'll need
- Everything verified in this guide: Git and Python 3.10 or newer. The skill's scripts use only the Python standard library. The verification environment ran Python 3.12.3. No account, no API key, no GPU for any step verified here.
- For the full agent-led dig: Claude Code (as a plugin) or Codex CLI (as a skill). Both need their own plan or API billing. The agent-led dig in Step 6 is described from the project's docs, not executed here — there is no Claude Code or Codex subscription in the verification environment — and every runnable step in this guide is quoted from actual runs.
- Optional, for richer source fetching:
pdftotext(poppler) for PDF text,pdftoppmplustesseractfor scanned PDFs,yt-dlpfor YouTube captions, andaxfor HTML-to-Markdown. Without them, the fetch script reports FAIL for that source type instead of silently degrading — a behaviour worth knowing before you point it at a PDF-heavy field. - One honest limitation, up front: the skill's instructions (
SKILL.md), its script messages, and its extract-page labels are in Japanese, and the author states it has only been tried with requests written in Japanese. An English README exists, and Claude reads instructions in any language, but expect a Japanese-flavoured workflow and labels. If that is a deal-breaker for your team, stop here; the rest of this guide will not talk you out of it.
Step 1 — Install the skill by hand (verified, no plugin manager needed)
The README documents three install routes: a Claude Code plugin marketplace entry, the skills CLI, and a manual copy. This guide verifies the manual route, because it works with nothing but Git and it puts the exact files on disk where you can inspect them:
git clone https://github.com/MaryCache/imozuru.git ~/src/imozuru
mkdir -p ~/.claude/skills
cp -r ~/src/imozuru/skills/imozuru ~/.claude/skills/imozuru
ls ~/.claude/skills/imozuru/scripts/
Expected output, verified October 29, 2026:
chain.py  dashboard.py  digest.py  fetch.py  make_guide_shots.py
make_textures.py  palette.py  report.py  skin.py  watch.py
For Codex CLI, the same folder goes to ~/.agents/skills/imozuru/ instead (or a symlink from the clone, as the README shows), and the skill is invoked as $imozuru rather than /imozuru. The plugin and skills-CLI routes are documented in the README and were not the verified path here: in the verification environment the skills CLI's clone step stalled against a full temporary directory, a sandbox condition, not a project defect. The manual copy avoids that dependency entirely, and it has a second advantage for a research tool: you can read SKILL.md before any agent ever runs it.
While you are here, inventory what you installed. The skill folder holds the instructions, a references folder with the theory, and the ten scripts above. The repository also ships eleven test files under tests/ and a bundled demo under examples/demo/ — the demo is what Step 2 runs, so you never have to take the verification logic on trust.
Step 2 — Run the machine check on the bundled demo (verified)
Before trusting any research tool, make it prove its checking works on data you did not create. imozuru's demo does exactly that: a small investigation with four extracts, saved sources, and a report builder that verifies every extract against its source before writing the page. Copy the demo somewhere writable first, so the original stays clean:
cp -r ~/src/imozuru/examples/demo ~/imozuru-demo
python3 ~/src/imozuru/skills/imozuru/scripts/report.py ~/imozuru-demo
ls -la ~/imozuru-demo/report.html
Expected output, verified October 29, 2026 (Python 3.12.3):
照合 OK: 抜き書き 4 件がすべて原文のとおり
→ ~/imozuru-demo/report.html
That line is the whole verification idea in one sentence: all four extracts match their originals exactly. The generated report.html is 128,443 bytes. Open it in a browser: it lists passages cut from the sources, point by point, each pointing at the file and lines it came from. Two notes for English-speaking readers. First, the demo investigation is Japanese — its topic is the order for shading with two colours — so the page title and labels are Japanese; the check itself is language-agnostic, comparing text against text. Second, this is the extract page, not a summary: nothing has been paraphrased, and that is the point. If an extract had been altered — version 2.2.0 fixed a case in which a dropped leading minus sign slipped through — the script would say so instead of building the page.
Step 3 — Collect every investigation on one dashboard (verified)
Version 2.0 added a dashboard that brings every investigation in a research folder together on one page, one topic each. Point it at the folder holding your demo copy:
python3 ~/src/imozuru/skills/imozuru/scripts/dashboard.py ~/imozuru-demo
ls -la ~/imozuru-demo/index.html
Expected output, verified October 29, 2026:
→ ~/imozuru-demo/index.html(調査 1件)The generated index.html is 630,787 bytes and summarises one investigation: why it stopped, where its sources came from, and how many rounds of following citations and links it took. Choosing a topic in the sidebar opens its details — research points, rounds, sources, documents — with the detailed report and extract page inside the same view. In real use the default research folder is ~/research, and the command is python3 skills/imozuru/scripts/dashboard.py ~/research, which writes ~/research/index.html. The sidebar search covers titles, questions, terms, people, and venues, and also matches hiragana and romaji — a small detail that matters once a folder holds investigations in two scripts.
What you have now, without any agent and without any API key, is the skill's output contract demonstrated end to end: sources saved verbatim, extracts machine-checked against them, and a dashboard that shows the whole investigation at a glance. That is the working result this guide promises. Everything after this step is the agent-led process that produces such folders at scale, and it is where the costs and caveats live.
Step 4 — Understand the dig before you launch one
An imozuru investigation is a folder, and knowing the folder is knowing the method. The README's layout for ~/research/<topic>/ is:
map.md         question, short title, research points, terms, people, venues, source table, next leads
log.md         per round: what was searched, what turned up, decisions and why
sources/       saved sources (no summaries)
extracts.json  extracts
report.html    extract page
queries.jsonl  every hit for every search query
fetch-log.jsonl fetch record (URL and OK/FAIL)
digest.json    explanation for the detailed report
digest.html    detailed report (explanations at three reader levels, plus the full search record)
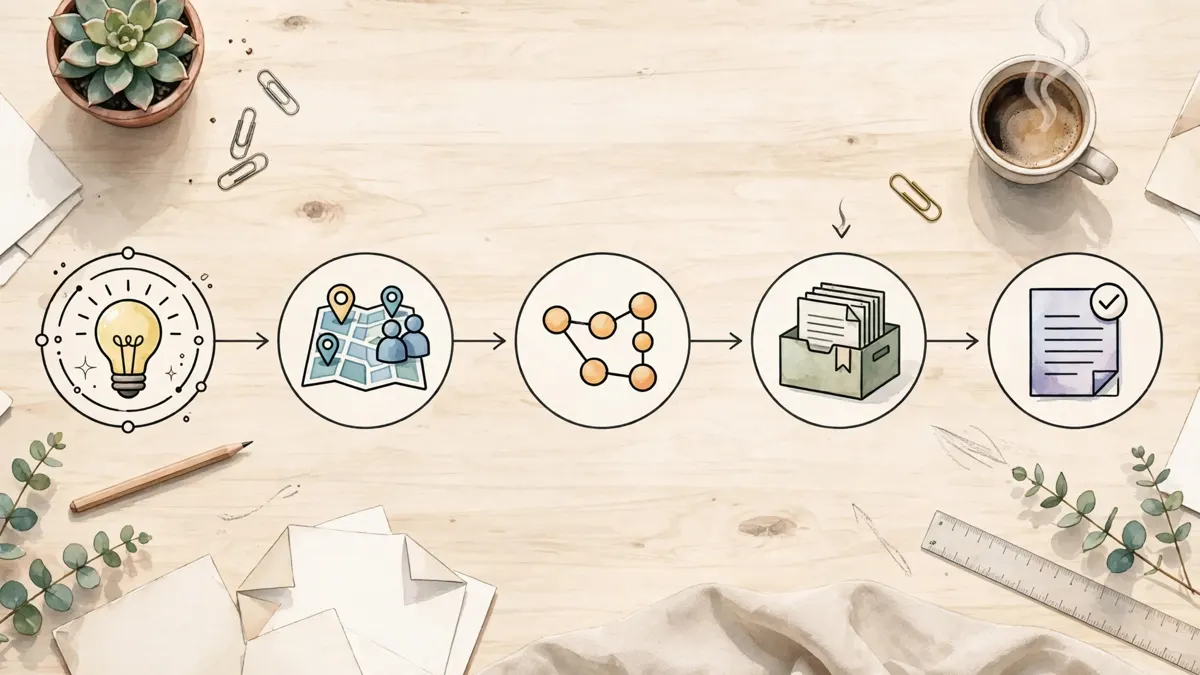
The flow, from the README and SKILL.md, runs in rounds. Round zero writes the question and three to six research points, then two searchers with different approaches — by default one English and one Japanese — collect the field's terms, central people, and venues into map.md. Later rounds follow citations, links, and authors: backwards through references, forwards through citing works, sideways through authors and venues. In fields without papers, the same moves follow links inside articles and notes such as "I based this on so-and-so's post". Sources are saved to sources/; 404 pages and login walls are dropped after checking their content. The search stops when every point has a source, or when no new sources turn up. Only then does the agent write the detailed report — explanations at three reader levels, every sentence carrying a quotation from a source as evidence, with the full search record attached — and digest.py checks every quotation against the sources before building the page.
Three design details deserve attention because they are where other research workflows quietly fail. First, searchers must report "found / looked but absent / not looked" separately, and the "not looked" items become the next leads — absence is tracked, not forgotten. Second, reports from searchers are treated as unconfirmed until the original is opened: the skill's own trials found searchers reporting zero opened originals, with affiliations and numbers wrong. Third, at least one research point must carry the request's own condition verbatim, not a weakened version of it — the skill's notes describe a trial in which all five points were phrased as "there is a …", so the investigation stopped after one round with the central condition untested. If you write your own points, copy that discipline: a point phrased as "there exists" will be satisfied by the first source that exists.
Step 5 — Follow citations with chain.py, and know its one live caveat
For fields with papers, the citation-following is partly a standalone tool, not just an agent behaviour. chain.py queries the OpenAlex API — no API key and no payment registration, per the script's own header — with four subcommands, shown by its help text:
chain.py find  <DOI or title>          … identify a paper, showing its ID (titles: top 5 candidates)
chain.py refs  <ID or DOI> [-n 20]    … backwards: the papers this paper cites
chain.py cites <ID or DOI> [-n 20]    … forwards: the papers citing this one, most-cited first
chain.py author <author name or ID> [-n 20] … follow an author, most-cited works first
Output is one paper per line, tab-separated: year, citation count, OpenAlex ID, title, DOI, and free PDF location. With --log <topic_dir> --round N, the listing is also appended to the investigation's queries.jsonl, so the citation trail becomes part of the auditable record rather than a chat aside.
Here is the caveat, stated exactly as observed. In the verification environment, chain.py returned an OpenAlex HTTP 429 (Too Many Requests) on three separate attempts — for a title search, a DOI reference lookup, and an author lookup — while a direct OpenAlex API call tagged with a contact address returned HTTP 200 with a real record in the same session. The script deliberately sends no contact address ("mailto omitted" in its User-Agent), so it draws from the anonymous pool, and this sandbox's shared egress address appears to have exhausted that pool's allowance. On your own connection, with your own address, expect it to work as documented; if you hit a 429, wait and retry rather than assuming the tool is broken, and note that the anonymous pool is shared. This guide does not quote a chain.py output it did not see, and the demo and dashboard steps above are the verified working result. The chain step is included because it is the skill's distinctive mechanism, documented in its help text and README — not because it was run here.
The same honesty applies to fetch.py, which downloads one source and checks it is genuine before keeping it. Its help text is explicit that login-walled sources fail rather than being faked: X returns FAIL because of its login wall, and Europe PMC's full-text XML substitutes for a captcha-blocked article page. The script also refuses private or internal destinations outright, a security rule with a real history in this codebase — its redirect handler follows redirects only within the OpenAlex origin, after a review found that a naive fetch could be redirected at a local service. For a tool that downloads whatever an agent points it at, that paranoia is a feature.
Step 6 — Run a real dig (documented path, not executed here)
With the skill installed and its output contract verified, the agent-led dig is the documented next step. In Claude Code, after the plugin install, you ask in the skill's own idiom — the README's examples include digging into Gaussian splatting from zero knowledge, and asking in what order skilled vocal-cover mixers apply their processing. In Codex CLI, the README's documented non-interactive form is:
codex --search exec -s workspace-write -c sandbox_workspace_write.network_access=true '$imozuru dig into this field: state management in React. Save results to ./research/react'That command is quoted from the README and was not executed in the verification environment, which has no Codex subscription; web search and network access for the source-fetching scripts are required, which is why the command enables both. A separate watch mode, /imozuru watch <topic>, runs apart from the dig flow: it collects new posts from the venues a dig turned up — Qiita and Zenn tags, note, YouTube, blogs, arXiv — via RSS and lists them. Start watch mode only after a dig has established the venues; watching a field you have not mapped yet just subscribes you to noise.
Judge a finished dig by its folder, not by its report. Open map.md and check that the research points carry your original conditions. Open log.md and check that "not looked" items were actually followed up. Open fetch-log.jsonl and count the FAILs — a dig with no FAILs in a hard field probably never tried the hard sources. Then read the extract page, and spot-check two extracts against their sources by the file and line numbers given. If any of those checks fails, the dig is not done, whatever the report's confidence sounds like.
When to use this vs alternatives
Use imozuru when you need to enter an unfamiliar field and be able to defend every claim from an original source afterwards — literature reviews, technical due diligence, learning a craft's practices from its practitioners, or any investigation where a wrong summary would cost more than a slow search. Its value is the audit trail: saved originals, machine-checked extracts, and a search record that shows what was not looked at.
Use a plain model summary when you need a quick orientation and the cost of being wrong is low. imozuru deliberately spends rounds and tokens to avoid premature closure; for "give me the gist of X", that machinery is pure overhead, and the skill itself says not to use it for single-fact lookups.
Use a deep-research product instead when you want a finished report with minimal supervision, or when you need English-first instructions and support. imozuru's instructions are Japanese, its author has only tried Japanese requests, and its agent loop needs a Claude Code or Codex subscription. A hosted deep-research tool trades away the local audit trail for convenience and language coverage; imozuru trades convenience for the trail.
Do not use imozuru as a citation generator. It saves sources and checks extracts, but it does not verify that a source is good, recent, or representative — that judgement is explicitly left to you, the reader of the originals. A folder full of verbatim extracts from weak sources is still a weak investigation, just a well-documented one.
The takeaway
imozuru is a small, new, opinionated skill: do not summarise during research, follow citations until every point has an original source or the trail goes cold, and machine-check every extract before anyone reads it. Verified here without any account or key: the manual install, the bundled demo's four extracts passing their machine check into a 128,443-byte report page, and the dashboard collecting that investigation into a 630,787-byte index. Not verified here, and stated as such: the agent-led dig itself, which needs a Claude Code or Codex subscription, and a live chain.py citation walk, which hit OpenAlex's anonymous-pool limit from this sandbox's shared address while a contact-tagged API call succeeded. Install it by hand, run the demo before you trust it, write research points that carry your real conditions, and judge every dig by its folder — sources, log, and FAILs — not by how polished its report sounds. The point of the tool is not a better summary. It is a summary you no longer need, because the originals are in your hands.
Sources: the MaryCache/imozuru repository (README.en, SKILL.md, script help texts, CHANGELOG, plugin.json, read October 29, 2026), the repository cloned and run for this guide (manual install and script listing, report.py demo output and report.html size, dashboard.py output and index.html size, chain.py HTTP 429 responses, and the contact-tagged OpenAlex API call returning HTTP 200, all quoted exactly), and the GitHub API for October 29, 2026 (1,369 stars, 65 forks, created October 13, 2026). The 1,173-new-stars trending figure is a third-party tracker's count cited in the guide; the agent-led dig and the Codex command in Step 6 are described from the project docs and were not executed here, because the verification environment has no Claude Code or Codex subscription.