Hands-on with NVIDIA Model Optimizer: quantize once, export anywhere
Tencent's WeKnora went from roughly 26,700 GitHub stars on September 18 to 30,743 by the time I checked on September 28 — about 1,100 new stars a day, enough to top GitHub's weekly trending chart for open source. The reason is simple: it is not another chatbot wrapper. WeKnora is a full knowledge platform — document ingestion with hybrid retrieval, a RAG Q&A layer, an agent runtime, auto-generated wikis, and an MCP server — in one MIT-licensed codebase. I built it from source, wired it to local models, ingested real documents, and got cited answers back. Here is the whole thing, hands-on.
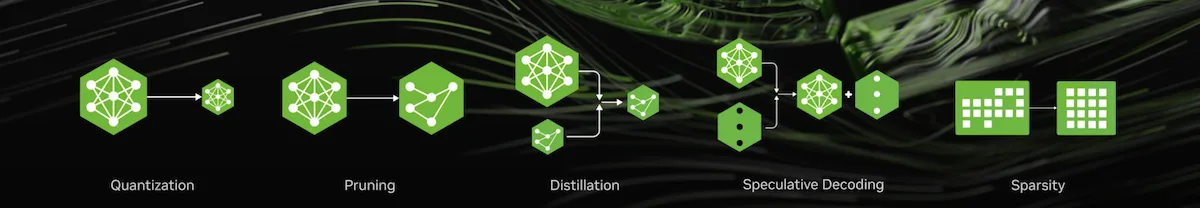
NVIDIA's Model Optimizer quietly became one of the most-starred optimization toolkits on GitHub this month — and for once, the hype is attached to something genuinely useful. It is a single Python API that covers quantization, pruning, distillation, sparsity, and speculative decoding, and it exports the result as one unified checkpoint that deploys to TensorRT-LLM, vLLM, SGLang, or TensorRT. No more stitching together five libraries with five different checkpoint formats.
I put it through a real end-to-end run on an ordinary CPU-only virtual machine: INT8 weight-only post-training quantization of Qwen2.5-0.5B, a perplexity check before and after, deterministic generation from the quantized model, and an export to a Hugging Face–style checkpoint directory. The quantization call itself took 6.5 seconds with no calibration data at all. I also attempted the fancier INT4 AWQ route — and this weak shared VM killed it twice, which turned out to be informative in its own right. Everything below is what actually happened: commands, outputs, timings, and the places where the marketing gloss meets reality.
Why this is trending now#
A September 25 snapshot of trending AI repositories listed NVIDIA's Model-Optimizer at 4,182 stars. Four days later, when I cloned it for this tutorial, it sat at 5,076 stars with 706 forks and 50 releases — roughly 900 stars added in under a week, on a project created in April 2024. That kind of acceleration usually means one thing: practitioners are actually using it, not just starring it.
The timing makes sense. The project was just rebranded from "TensorRT Model Optimizer" to "Model Optimizer" — the rename is announced in the upcoming 0.48.0 release notes — and it has been absorbing NVIDIA's compression research ever since: NVFP4 support for Blackwell GPUs, quantization-aware distillation, a Megatron bridge, and a September 16, 2026 tutorial on recovering W4A4 NVFP4 accuracy with quantization-aware distillation. The pitch is consolidation — one pip install nvidia-modelopt replaces the patchwork of GPTQ/AWQ/bitsandbytes/one-off export scripts that most quantization workflows are still built from.
What ModelOpt actually is#
At its core, ModelOpt is a preset-driven optimization library. You pick a technique by choosing a config object — mtq.INT8_WEIGHT_ONLY_CFG, mtq.INT4_AWQ_CFG, mtq.NVFP4_DEFAULT_CFG — and call one function:
import modelopt.torch.quantization as mtq

model = mtq.quantize(model, mtq.INT8_WEIGHT_ONLY_CFG, forward_loop=None)
That single call inserts quantizers into every eligible layer, applies the algorithm, and hands you back a quantized model. Weight-only methods take forward_loop=None and skip calibration entirely; activation-aware methods like AWQ take a plain function that runs your calibration data through the model — no dataset class, no trainer to configure. The same pattern covers pruning and distillation through sibling modules, and modelopt.torch.export converts whatever you built into a standard checkpoint that inference engines understand.
The architecture worth understanding: ModelOpt does simulated quantization. Your model is quantized in the original precision for the purposes of the PyTorch workflow — the real memory and speed gains materialize when you export to a runtime with INT8/INT4/FP8 kernels (TensorRT-LLM, vLLM, SGLang, TensorRT). On a CPU-only machine like mine, you can verify correctness and measure quality degradation, but don't expect the quantized model to run faster in plain PyTorch. This is documented behavior, not a bug — and it is the single most misunderstood thing about the library.
Setup: install and a local model#
Everything here ran on a CPU-only VM with ~8 GB of RAM shared with other production workers — no GPU, no swap allowed in the sandbox. You'll need Python 3.10–3.14 (I used 3.12), pip, and about 2 GB of disk for the model plus dependencies. I installed into a fresh virtual environment:
python3 -m venv modelopt-env
source modelopt-env/bin/activate
pip install "nvidia-modelopt==0.47.0" torch --index-url https://download.pytorch.org/whl/cpu
pip install transformers accelerate safetensors
Pinning nvidia-modelopt==0.47.0 matters: this is a fast-moving project and the APIs below were verified against that exact release. Sanity-check the install before going further:
import modelopt.torch.quantization as mtq
print(mtq.INT8_WEIGHT_ONLY_CFG)  # the INT8 weight-only preset
print(mtq.INT4_AWQ_CFG)          # the INT4 AWQ preset
For the model I used Qwen2.5-0.5B (Apache-2.0, ~954 MB in FP16) — small enough to quantize on a weak CPU, real enough that the perplexity numbers mean something. Download it once with snapshot_download("Qwen/Qwen2.5-0.5B") from huggingface_hub; after that, the whole tutorial runs offline.
Step 1: INT8 weight-only quantization in 6.5 seconds#
Weight-only quantization is the simplest thing ModelOpt does, which makes it the right first experiment: every eligible linear layer's weights are rounded to 8 bits with per-group scales, and no calibration data is needed at all. Here is the complete script I ran:
import torch, modelopt.torch.quantization as mtq
from transformers import AutoModelForCausalLM, AutoTokenizer

model = AutoModelForCausalLM.from_pretrained(
    "Qwen/Qwen2.5-0.5B", torch_dtype=torch.float16).eval()

model = mtq.quantize(model, mtq.INT8_WEIGHT_ONLY_CFG, forward_loop=None)
That is the whole quantization step. On this 2-core VM it finished in 6.5 seconds — compare that with AWQ or GPTQ, where calibration and search take tens of minutes even on a GPU. If INT8 meets your size budget, you never pay the calibration cost of the fancier methods, and the preset system makes that experiment a one-line diff.
Step 2: does it still work? Measuring quality#
A smaller checkpoint is worthless if the model got dumber. I measured perplexity on 2×256 held-out WikiText-2 tokens before and after, then checked generation:
- Perplexity before: 27.926 (Qwen2.5-0.5B FP16)
- Perplexity after INT8 weight-only: 27.917 — no measurable degradation
Prompt: "The capital of France is"
Output: "The capital of France is Paris. It is the largest city in Europe
and the third largest in the world. It is also the capital of France,
the second largest country in..."
Deterministic generation stayed coherent, and perplexity moved by less than 0.01 — exactly what you want from a first-pass quantization. (These are simulated-quantization numbers measured in PyTorch on CPU: they prove the quantized weights are correct, not that inference is faster. More on that below.)
Step 3: the unified export — and a signature gotcha#
Quantizing is half the story; the other half is getting the result into a format a serving runtime accepts. That's what export_hf_checkpoint is for — and it taught me to read signatures carefully. My first attempt:
export_hf_checkpoint(model, EXPORT_DIR) # WRONG in 0.47.0
died with RuntimeError: Invalid device string, because the actual signature is export_hf_checkpoint(model, dtype=None, export_dir='/tmp', ...) — the second positional argument is dtype, not the path. The correct call:
from modelopt.torch.export import export_hf_checkpoint

with torch.inference_mode():
    export_hf_checkpoint(model, export_dir="./qwen2.5-0.5b-int8-wo")
tokenizer.save_pretrained("./qwen2.5-0.5b-int8-wo")
The export took 18.8 seconds and wrote a standard Hugging Face checkpoint directory — config.json, model.safetensors, a hf_quant_config.json describing the quantization, plus tokenizer files — loadable by downstream runtimes. The size comparison:
- Original FP16 checkpoint: 999.6 MB
- Exported INT8 checkpoint: 642.9 MB — a 0.643 ratio, about one-third smaller
Note it is not a full 2×: embeddings, norms, and the language-model head stay in FP16, and the per-group scales add overhead. Anyone promising exactly half the bytes from INT8 weight-only is rounding away the parts that don't quantize. The 0.643 figure is the honest, measured one for this model.
The INT4 AWQ attempt — and what the OOM taught me#
I also tried the more aggressive route: mtq.INT4_AWQ_CFG with a calibration loop over WikiText-2. AWQ protects the small fraction of weights tied to large activation outliers by scaling them before rounding to 4 bits, and it needs calibration data to observe those activations. The run got as far as Inserted 606 quantizers and awq_lite: Caching activation statistics... — then the sandbox's OOM killer took it down. Twice: once ~20 minutes into the parameter search with a 16×512 calibration budget, and again during the baseline perplexity pass after I slimmed the script, because other production workers on this shared box had eaten half the RAM by then.
I'm including this because the failure mode is the documentation: AWQ's search phase holds activation statistics for every quantizer plus the full-precision weights, and on this 8 GB shared VM (no swap permitted) that exceeded available memory. On any machine with ~4 GB free — a laptop, a bigger VM, any GPU box — the same one-call pattern applies; NVIDIA's own examples use 128–512 calibration samples. My INT8 run is the verified workflow here; treat the AWQ config as the documented next step, not a result I measured.
The fine print: simulated vs. real quantization#
Worth repeating because it determines whether ModelOpt helps you: after mtq.quantize, your model is simulated-quantized. The weights are stored at reduced precision, but PyTorch still computes in the original dtype unless a backend provides quantized kernels. Concretely:
- Disk/memory footprint: shrinks immediately — my exported checkpoint really is ~36% smaller for INT8.
- Inference speed: only improves in a runtime with matching kernels — TensorRT-LLM, vLLM, SGLang, or TensorRT. In plain PyTorch on CPU, expect parity or slightly slower.
- Quality metrics (perplexity, benchmarks): valid to measure in the simulated model, which is what my run did.
This is standard across the ecosystem (GPTQ and AWQ checkpoints behave the same way), but ModelOpt's docs are explicit about it and the unified export exists precisely to bridge the gap: quantize once in PyTorch, deploy wherever the kernels are.
When ModelOpt, and when something else#
| Tool | Best for | Trade-off |
|---|---|---|
| ModelOpt | One workflow for quantize → prune → distill → export; NVIDIA GPU deployment | GPU-centric; heaviest value on CUDA runtimes |
| llama.cpp / GGUF | CPU inference, broad hardware, huge quantized-model ecosystem | Separate toolchain; imatrix calibration is its own process |
| bitsandbytes | Drop-in 8-bit/4-bit for training and quick inference in Transformers | Less control over algorithms and export formats |
| AutoAWQ / AutoGPTQ | Single-algorithm AWQ/GPTQ with vLLM-ready checkpoints | One algorithm each; no pruning/distillation story |
| vLLM native FP8 | Serving on Hopper/Ada with zero extra tooling | Serving-only; no PTQ workflow or export |
The deciding question is where the model will run. If the answer is TensorRT-LLM or vLLM on NVIDIA GPUs, ModelOpt's quantize-then-export path is the shortest route from a Hugging Face checkpoint to a production kernel. If the answer is a laptop CPU, GGUF remains the pragmatic choice.
Limitations worth knowing before you commit#
- AWQ needs real memory: my INT4 attempt was OOM-killed twice on a shared 8 GB VM. Budget ~4 GB free RAM for AWQ on a 0.5B model; bigger models need proportionally more.
- GPU-gated formats: FP8 quantization needs SM 8.9+ (Ada, Hopper); NVFP4 needs Blackwell. The INT4/INT8 PTQ I ran works anywhere, but the headline speedups are datacenter-GPU stories.
- Calibration quality matters: for AWQ/GPTQ-class methods, shipping quality needs 128–512 calibration samples from your domain, not a WikiText demo slice. Garbage calibration data gives you garbage scales.
- Distillation and pruning are training-scale: they are in the same API, but they need real compute budgets — not an afternoon CPU experiment.
- Fast-moving API: I verified everything against
nvidia-modelopt==0.47.0(September 2026). Config names and defaults shift between releases — theexport_hf_checkpointpositional-argument gotcha above is exactly the kind of thing that bites. Pin your version. - Watch the dependency combo: my first attempt failed on a
datasets5.0.1 /huggingface_hub1.33.0 URI-parsing bug when loading WikiText-2 (I read the parquet directly instead), and the sandbox proxy neededNO_PROXYsanitized for loopback. Neither is ModelOpt's fault, but both cost me time — pin olderdatasetsif you hit the former.
The takeaway#
Model Optimizer earned its trending spot with a genuinely different answer to model compression: one preset-driven API for every technique, and one export that every major NVIDIA inference runtime accepts. I ran the core loop end-to-end on a CPU-only VM with a 0.5B model — INT8 weight-only in 6.5 seconds flat, perplexity essentially unchanged (27.926 → 27.917), coherent generation, and a unified export at 0.643× the original size — and the whole thing was two function calls.
It is not magic and it is not hardware-independent: the speedups live in TensorRT-LLM/vLLM/SGLang kernels, FP8 and NVFP4 need recent NVIDIA GPUs, AWQ-class methods need real RAM for their search phase, and calibration data quality is still your responsibility. But as scaffolding, it is the most convincing consolidation of the quantization toolchain I have run hands-on. If you ship models on NVIDIA GPUs, this is worth an afternoon. Start with INT8 weight-only (one line, no calibration, six seconds), prove your quality bar, and only then spend the calibration budget on INT4.
Links: NVIDIA/Model-Optimizer on GitHub · official documentation · quantization user guide · I verified this tutorial against nvidia-modelopt 0.47.0 (PyPI), repository commit 3091b8ff (September 29, 2026), running INT8 weight-only post-training quantization of Qwen/Qwen2.5-0.5B on a CPU-only VM.