Stop burning tokens on grep: give your coding agent a local search engine with XERJ
Your coding agent burns thousands of tokens reading whole files just to find three lines of code. XERJ indexes your project once — BM25, vector, and hybrid search behind an Elasticsearch-compatible API — and hands your agent exactly the passages it needs over MCP. Here is how to install it, wire it in, and measure the savings.
- What: XERJ (xerj-org/xerj) — a local-first search engine and MCP server for AI agents, Apache-2.0 licensed.
- Traction: 12,600+ GitHub stars and 777 forks as of Oct 21, 2026; the project dates to June 2026.
- Payload: one static Rust binary, no JVM, no dependencies — prebuilt for Linux, macOS, and Windows on x86-64 and arm64.
- Retrieval: BM25 full-text + kNN vector + hybrid search, tree-sitter code search with go-to-definition, a
/_memorynamespace for agent memory, and an Elasticsearch-compatible API. - Measured savings: 2.7× fewer output tokens at the same 16/16 solve rate in the project's controlled case study (8 tasks, 4 languages); users report roughly 5× in everyday work.
- Defaults: the lexical embedder runs fully offline with no downloads; the neural embedder is opt-in (~90MB). A fresh node binds 127.0.0.1 and serves on port 9200.
What you’ll need
- A Mac, Linux, or Windows machine (x86-64 or arm64) — no GPU required.
- A code folder to index. Your own project is ideal; the wins are biggest on private, niche, or post-cutoff code.
- A coding agent with MCP support: Claude Code, Cursor, or any MCP client.
- About two minutes.
Step 1 — Install XERJ
One command on macOS or Linux:
curl -fsSL https://xerj.org/get | shOn Windows PowerShell:
irm https://xerj.org/get.ps1 | iexThat’s the whole install: one static Rust binary, no JVM, no dependencies. The installer prints where xerj landed — add it to your PATH if needed. You can also build from source; the README documents it.
Step 2 — Start the engine and index a project
xerj --insecure --data-dir ~/xerj-data &Wait until http://localhost:9200 responds, then index any folder:
xerj autoindex ~/my-projectTwo things to know before you run it. First, keep that data directory outside any folder you will autoindex — data/ is not in the built-in ignore list, so --data-dir ./data inside a tree you then index makes the node index its own storage. Second, that --insecure flag is a trust boundary, not a formality: it turns off TLS and API-key auth, so every caller that can reach the port is a superuser who can read and delete every index. It is meant for one user on a dev machine — a fresh node binds 127.0.0.1 only, and a cleartext bind on any other interface refuses to start unless you explicitly allow it.
Step 3 — Search and jump to definitions from the CLI
xerj search "how do we rotate the WAL segment"   # ranked passages, file:line
xerj def "euler_to_rotationmatrix"               # go-to-definition: file:line + signature
Under the hood you get BM25 full-text, kNN vector, and hybrid search, tree-sitter-powered code search, and a /_memory namespace for agent memory. It speaks the Elasticsearch API, so existing clients, dashboards, and tooling work against it unchanged. The default embedder is lexical and fully offline — nothing to download; a neural embedder is opt-in at about 90MB.
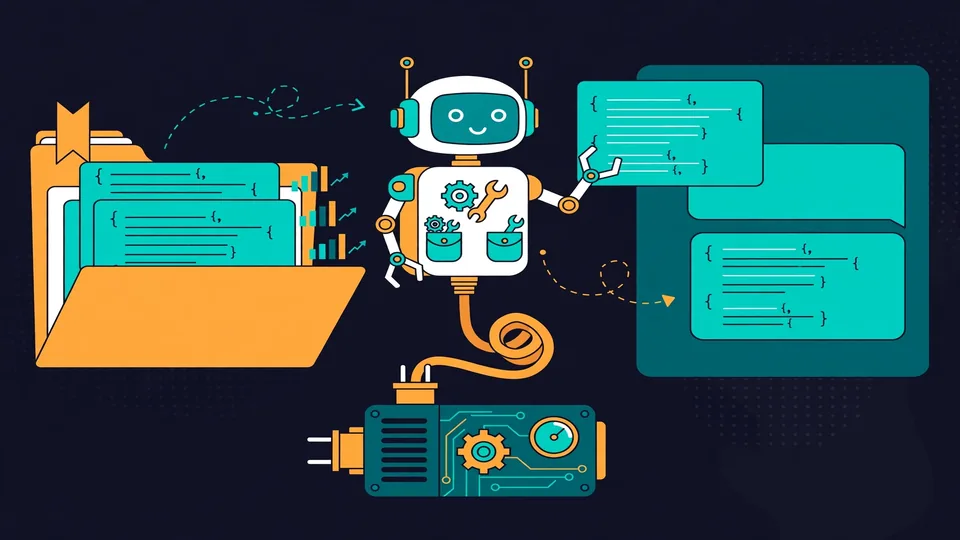
Step 4 — Wire it into Claude Code or Cursor as an MCP server
xerj init # wire XERJ into Claude Code/Cursor (MCP + skill), one commandOne command installs the MCP server and the skill. From then on your agent queries the index itself — no more reading whole files to find three lines of code.
Step 5 — Try “reference coding” and measure the savings
Reference coding is XERJ’s headline use case: the agent clones the open-source repos closest to your task, indexes them, and searches how they solved the problem before writing its own code. In the project’s controlled case study (8 tasks, 4 languages, real token counts), agents using XERJ cut output tokens 2.7× at the same 16/16 solve rate; field reports from everyday users land around 5×.
After a session, ask what it did for you:
xerj gain # what it did for you — counted, not estimatedThe number is counted from your actual usage, not estimated.
What you built
A local-first search engine on your own machine: your code, docs, and logs indexed for BM25, vector, and hybrid retrieval; a go-to-definition CLI; an MCP server your coding agent queries itself; and a running counter of the tokens it saved you.
Honest limitations
- Value is gated by memorization. The project says it plainly: XERJ wins on private, internal, niche, or post-cutoff code, and is neutral to harmful on popular public libraries the model already knows. Point it at your own codebase, not at React.
--insecureis the price of zero-config. No TLS, no auth. Fine on 127.0.0.1 on your own machine — never expose the port to a network.- It’s a single-user dev tool, not a server. A cleartext bind on any interface other than localhost refuses to start unless you explicitly allow it. Plan multi-user deployments accordingly.
Frequently asked questions
What does the --insecure flag actually do?
It disables TLS and API-key authentication, so every caller that can reach the port is a superuser who can read and delete every index, including every /_memory namespace. The project treats it as a trust boundary, not a formality: it is meant for one user on a dev machine, a fresh node binds 127.0.0.1 only, and a cleartext bind on any other interface refuses to start unless you explicitly allow it.
Do I need a GPU or model downloads to run XERJ?
No. The default embedder is lexical and runs fully offline — nothing to download and no GPU. A neural embedder is available opt-in and pulls about 90MB. The whole engine ships as one static Rust binary with no JVM and no dependencies.
Where does XERJ help most — and where doesn't it?
In the project's own words, the value is gated by memorization: it wins on private, internal, niche, or post-cutoff code, and is neutral to harmful on popular public libraries the model already knows. Reference coding — indexing the open-source repos closest to your task so the agent reuses how they solved the problem before writing its own code — is the clearest win.